SNOBOL4 built-in string transformation functions. More...
#include <stdbool.h>#include <stddef.h>#include <stdint.h>#include "snobol/snobol_attrs.h"#include "snobol/vm.h"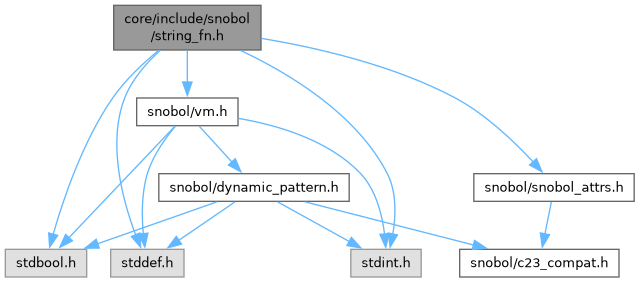
Go to the source code of this file.
Functions | |
| size_t | snobol_size (const char *str, size_t len) |
| bool | snobol_trim (const char *in, size_t in_len, snobol_buf *out) |
| bool | snobol_dupl (const char *str, size_t str_len, size_t n, snobol_buf *out) |
| bool | snobol_reverse (const char *str, size_t str_len, snobol_buf *out) |
| bool | snobol_substr (const char *str, size_t str_len, size_t pos, size_t len, snobol_buf *out) |
| bool | snobol_replace (const char *str, size_t str_len, const char *from, size_t from_len, const char *to, size_t to_len, snobol_buf *out) |
| bool | snobol_replace_char (const char *str, size_t str_len, const char *from, size_t from_len, const char *to, size_t to_len, snobol_buf *out) |
| bool | snobol_lpad (const char *str, size_t str_len, size_t width, uint32_t pad_cp, snobol_buf *out) |
| bool | snobol_rpad (const char *str, size_t str_len, size_t width, uint32_t pad_cp, snobol_buf *out) |
| bool | snobol_char_fn (uint32_t cp, snobol_buf *out) |
| bool | snobol_ord (const char *str, size_t str_len, uint32_t *out_cp) |
| bool | snobol_upper (const char *str, size_t str_len, snobol_buf *out) |
| bool | snobol_lower (const char *str, size_t str_len, snobol_buf *out) |
Detailed Description
SNOBOL4 built-in string transformation functions.
All functions operate on UTF-8 encoded strings. Codepoint semantics: positions and lengths are in Unicode codepoints, not bytes. ASCII fast path: if all bytes are < 0x80, faster byte-level operations are used.
Output is always written to a snobol_buf (from vm.h). Functions return true on success, false on error/invalid input.
Definition in file string_fn.h.
Function Documentation
◆ snobol_char_fn()
| bool snobol_char_fn | ( | uint32_t | cp, |
| snobol_buf * | out ) |
CHAR: convert a Unicode codepoint to a UTF-8 string.
- Parameters
-
cp Unicode codepoint (0 to 0x10FFFF) out Output buffer
- Returns
- true on success, false if cp > 0x10FFFF or is a surrogate
◆ snobol_dupl()
| bool snobol_dupl | ( | const char * | str, |
| size_t | str_len, | ||
| size_t | n, | ||
| snobol_buf * | out ) |
DUPL: duplicate a string n times. Pre-allocates the output buffer.
- Parameters
-
str Input string str_len Byte length of input n Number of copies out Output buffer
- Returns
- true on success
◆ snobol_lower()
| bool snobol_lower | ( | const char * | str, |
| size_t | str_len, | ||
| snobol_buf * | out ) |
LOWER: convert string to lowercase. Full BMP case folding via snobol_to_lower_cp(). Astral plane codepoints (U+10000+) are passed through unchanged.
- Parameters
-
str Input string str_len Byte length out Output buffer
- Returns
- true on success
◆ snobol_lpad()
| bool snobol_lpad | ( | const char * | str, |
| size_t | str_len, | ||
| size_t | width, | ||
| uint32_t | pad_cp, | ||
| snobol_buf * | out ) |
LPAD: left-pad a string to [width] codepoints using [pad_cp] as fill character. If string is already as wide as or wider than [width], returns the string unchanged.
- Parameters
-
str Input string str_len Byte length width Target width in codepoints pad_cp Pad character as Unicode codepoint out Output buffer
- Returns
- true on success
◆ snobol_ord()
| bool snobol_ord | ( | const char * | str, |
| size_t | str_len, | ||
| uint32_t * | out_cp ) |
ORD: get the Unicode codepoint of the first character in a string.
- Parameters
-
str Input string (UTF-8) str_len Byte length out_cp Output codepoint
- Returns
- true on success, false if string is empty or invalid UTF-8
◆ snobol_replace()
| bool snobol_replace | ( | const char * | str, |
| size_t | str_len, | ||
| const char * | from, | ||
| size_t | from_len, | ||
| const char * | to, | ||
| size_t | to_len, | ||
| snobol_buf * | out ) |
REPLACE: replace all occurrences of [from] with [to]. O(n*m) where m is the number of occurrences.
- Parameters
-
str Input string str_len Byte length from Pattern to find from_len Byte length of pattern to Replacement string to_len Byte length of replacement out Output buffer
- Returns
- true on success
◆ snobol_replace_char()
| bool snobol_replace_char | ( | const char * | str, |
| size_t | str_len, | ||
| const char * | from, | ||
| size_t | from_len, | ||
| const char * | to, | ||
| size_t | to_len, | ||
| snobol_buf * | out ) |
REPLACE_CHAR: character-by-character translation using a 256-byte lookup table. Equivalent to POSIX tr. Each character in [from] is replaced by the corresponding character in [to]. Characters in [from] beyond the length of [to] are left unchanged. O(n) single-pass implementation.
- Parameters
-
str Input string str_len Byte length from Characters to translate from_len Length of [from] to Replacement characters to_len Length of [to] out Output buffer
- Returns
- true on success
◆ snobol_reverse()
| bool snobol_reverse | ( | const char * | str, |
| size_t | str_len, | ||
| snobol_buf * | out ) |
REVERSE: reverse a string by Unicode codepoints (not bytes). Two-pass implementation: first collect codepoint spans, then reverse.
- Parameters
-
str Input string (UTF-8) str_len Byte length out Output buffer
- Returns
- true on success
◆ snobol_rpad()
| bool snobol_rpad | ( | const char * | str, |
| size_t | str_len, | ||
| size_t | width, | ||
| uint32_t | pad_cp, | ||
| snobol_buf * | out ) |
RPAD: right-pad a string to [width] codepoints using [pad_cp] as fill character. If string is already as wide as or wider than [width], returns the string unchanged.
- Parameters
-
str Input string str_len Byte length width Target width in codepoints pad_cp Pad character as Unicode codepoint out Output buffer
- Returns
- true on success
◆ snobol_size()
| size_t snobol_size | ( | const char * | str, |
| size_t | len ) |
SIZE: count Unicode codepoints (not bytes). ASCII fast path: if all bytes < 0x80, returns byte length directly.
- Parameters
-
str Input string (UTF-8, not required to be null-terminated) len Byte length of str
- Returns
- Number of Unicode codepoints
◆ snobol_substr()
| bool snobol_substr | ( | const char * | str, |
| size_t | str_len, | ||
| size_t | pos, | ||
| size_t | len, | ||
| snobol_buf * | out ) |
SUBSTR: extract substring by 1-based codepoint position and codepoint length.
- Parameters
-
str Input string (UTF-8) str_len Byte length pos 1-based codepoint position (1 = first character) len Maximum number of codepoints to extract out Output buffer
- Returns
- true on success, false if pos is out of range
◆ snobol_trim()
| bool snobol_trim | ( | const char * | in, |
| size_t | in_len, | ||
| snobol_buf * | out ) |
TRIM: remove trailing whitespace (space, tab, CR, LF). Unicode-aware: stops at first non-whitespace from the right.
- Parameters
-
in Input string in_len Byte length of input out Output buffer (cleared and filled)
- Returns
- true always (function cannot fail on valid input)
◆ snobol_upper()
| bool snobol_upper | ( | const char * | str, |
| size_t | str_len, | ||
| snobol_buf * | out ) |
UPPER: convert string to uppercase. Full BMP case folding via snobol_to_upper_cp(). Astral plane codepoints (U+10000+) are passed through unchanged.
- Parameters
-
str Input string str_len Byte length out Output buffer
- Returns
- true on success